Kinds of Waiting — Measuring Before Choosing a Performance Fix
 Photo by You Know What Blog on Pexels
Our document detail page is server-rendered, its content arrives quickly, and its headline metric looks perfectly respectable. It also feels slow, because the revision switcher, which is the control the whole page exists for, doesn’t respond for a while after everything appears to be finished.
That gap between “looks fast” and “is usable” is what this article is about. The method is thoroughly unexciting, and actually following it is what makes the difference: work out which kind of waiting you’ve got, change the thing that causes that kind, and then measure again at the same boundary.
The examples come from the fictional document application, and the illustrations are drawn rather than captured. Where I describe effects, I describe them as kinds of work avoided rather than as measurements.
Table of Contents
- A Page That Looks Fast and Feels Slow
- Naming the Kinds of Waiting
- Measuring Before Deciding
- Server Work: Not Doing It Twice
- Main-Thread Work: Scheduling Hydration
- Resource Discovery: Images
- Fonts and Layout Stability
- Third-Party Scripts and Audit Parity
- Bundles: Import Boundaries Rather Than Chunk Counts
- Rewriting the Rendered HTML
- Verifying the Combined Result
- What’s Next
A Page That Looks Fast and Feels Slow
Three different things can make the same page unsatisfying, and they’ve got nothing whatsoever to do with each other:
- the server took a long time to produce the HTML;
- the HTML arrived quickly but the largest visible element appeared late, because a font, an image or a stylesheet was discovered late;
- everything was visible quickly and the page ignored input, because the main thread was busy executing and hydrating JavaScript.
Only the third one describes our revision switcher. Optimizing the first, so caching harder and tuning the gateway, would be a great deal of work with no effect at all on the actual complaint. That’s the most common way I’ve seen performance effort get wasted, and it’s the reason the rest of this article starts with measurement rather than with techniques.
Naming the Kinds of Waiting
Each signal answers exactly one question and stays completely silent about the others. Confusing them is what produces the “we improved the score and the users noticed nothing” outcome.
| Signal | What it helps explain | What it does not establish |
|---|---|---|
| HTTP response duration | Server and transport work at a chosen boundary | Anything about rendering or interactivity |
| First Contentful Paint | When something appeared | Whether it was the content or the controls |
| Largest Contentful Paint | When the largest qualifying element rendered | Whether the page responds to input |
| Cumulative Layout Shift | Unexpected movement of content | Load speed |
| Total Blocking Time | Blocking portions of long tasks in a lab window | All of the delay between visible and usable |
| Interaction to Next Paint | Responsiveness of real interactions in the field | Which code caused a slow interaction |
Our switcher problem lives in the last two rows, and it’s completely invisible in the second and third. Which is precisely how a page manages to pass an audit and annoy its users at the same time.
Measuring Before Deciding
Two habits are what make the numbers usable.
Record the conditions along with the result. Device profile, network throttling, cache state, consent state and the version of the audit tool all change the outcome. A result without those can’t be compared to anything at all, including a later run of itself.
Repeat, and compare distributions rather than single runs. Browser measurements are noisy enough that one run can shift a headline number by a bigger margin than the change you’re trying to evaluate. If you can’t see a change across repeated runs, then you haven’t demonstrated it.
And for anything you publish, describe effects as ranges or as the class of work avoided, so “one fewer connection setup on the critical path” or “several hundred kilobytes no longer parsed during startup”, rather than as precise figures from one particular deployment.
Server Work: Not Doing It Twice
If the measurement points at response duration, then the question is what work the server is doing that it already did before. The series has built most of the answer already: the in-process gateway from Part 2 takes away a loopback HTTP hop but not the remote calls, and the operation and result-set caches from Parts 3 and 9 take away repeated fetching when, and only when, their cache identity is right.
Two things are worth keeping in view while you tune this. The three cache levels, being page result set, operation result and rendered HTML, all have different identities, and the deeper you cache the more inputs the key has to include. Rendered HTML in particular varies by experiment assignment and by every single Part 10 condition. And the cold path still exists, so every measurement of a warm cache is a measurement of the good case. Measure both, because the cold path is what a deployment or an invalidation hands you, and it’s what a traffic spike is going to find.
Main-Thread Work: Scheduling Hydration
If the measurement points at blocking time or interaction latency, then the cost is JavaScript executing during startup, and hydration is usually the single largest contributor to it.
Component-level lazy hydration, where your framework supports it, is the controllable version of this: one specific component waits for one specific trigger. Deferring the whole entry script is a far more invasive change which interacts with navigation, preload hints, content security policy and build output, and it’s very easy to do in a way that merely moves work outside an audit’s measurement window.
Keep that distinction in view, because deferring work and removing work are not at all the same thing. Deferred work still runs. It runs later, and the visitor may well be sitting there waiting for it by then. A visitor who clicks the revision switcher before it hydrates still needs that click to do something. Part 14 is entirely about choosing those boundaries, so the rule here is simply this: don’t defer the control the page exists for.
There are two mechanisms in this area that people commonly misread.
A prefetch hint is a hint. <link rel="prefetch"> tells the browser that a resource might be useful soon, and the browser decides whether to fetch it. It may skip it entirely under memory pressure, on a metered connection, or because more urgent work is queued up. Code that assumes a prefetched chunk is already local still has to work when it isn’t.
The other one is the belief that awaiting a promise gives the browser room to breathe. It doesn’t, and the reason lies in how the event loop is structured. The browser runs one task at a time, whether that’s a script, an event handler or a timer callback, and it can only style, lay out and paint between tasks. Promise continuations are microtasks, and the microtask queue gets drained to exhaustion at the end of the current task, before the browser ever regains control. So this hydrates everything in one uninterrupted block, despite looking for all the world like it spreads the work out:
for (const component of components) {
  await Promise.resolve()   // microtask: no paint happens here
  hydrate(component)
}
To actually yield, the work has to end the current task and continue in a later one, using setTimeout, requestIdleCallback, requestAnimationFrame, or scheduler.yield() and scheduler.postTask() where they’re available. And that’s a genuine difference in what the visitor experiences: the same total work, but in slices the browser can interleave with painting and input handling, instead of one long block during which the page cheerfully ignores clicks.
Resource Discovery: Images
If the largest element on the page is an image from a third-party origin, then part of its cost is connection setup: DNS, TCP and TLS to a host the browser hasn’t talked to yet, all sitting on the critical path.
Serving that image through your own origin takes that away, because the connection already exists and a configured edge cache can hand over the bytes:
Do notice what that diagram doesn’t contain: a local cache in the reverse proxy. Forwarding requests and setting cache headers is not the same thing as holding responses, so whether anything actually gets cached depends on the edge configuration and on the response’s own cache semantics. Go and check that rather than assuming it.
Two obligations come along with a route like this. It has to validate the path and the parameters and restrict upstream destinations to an allowlist, or what you’ve built is an open proxy, and it will be found and used. And it has to preserve the content type and the upstream’s cache validators, meaning the ETag and Last-Modified headers a browser sends back to ask “I already have this version, has it changed?”, which is what turns a repeat request into a cheap 304 Not Modified instead of a full download. Drop those and every revisit re-downloads the image.
The related decision is how long to allow caching for. A long max-age with immutable tells browsers and edge caches never to revalidate, which is ideal for a URL whose content can never change, like a hashed filename, and a trap for a stable URL whose content can, because you then have no way of correcting a wrong image short of waiting out the lifetime everywhere. Long-lived immutable caching is safe exactly when a content change produces a new URL.
The benefit here is workload-dependent. A saved connection matters most on a constrained mobile connection and least on a warm desktop cache, while a miss adds server-side forwarding work. When proxying adds more complexity than it takes away, a preconnect hint is the simpler intervention: it overlaps connection setup with other work without putting your server in the image path at all.
Fonts and Layout Stability
Web fonts trade three things off against each other: how soon the text is readable, whether it looks right, and whether it moves about. A fallback font with similar metrics cuts down the movement when the web font takes over, and font-display: optional avoids a late swap altogether at the cost of some visits never seeing your web font at all.
@font-face {
  font-family: 'Example Sans';
  src: url('/fonts/example-sans.woff2') format('woff2');
  font-display: optional;
}
Preload only what you need above the fold, and go and measure the actual fallback metrics for your own typefaces rather than copying adjustment percentages out of an article about entirely different ones. And keep the scope honest: fonts are one source of layout shift among several, sitting alongside images without intrinsic dimensions, late-inserted banners and consent dialogs.
Third-Party Scripts and Audit Parity
Analytics, tag managers and support widgets are the easiest performance wins going, because a great deal of what they cost you is optional. Load them only when the visit actually needs them and consent permits it, and schedule them out of the startup path:
Idle scheduling helps, and it guarantees nothing at all: an idle callback can still run while a user is trying to interact, and a timeout is not a promise about main-thread availability.
And one practice deserves naming as the anti-pattern it is. Detecting audit tools by user agent, disabling expensive features for them, and then publishing the resulting score, measures a configuration that no visitor ever experiences. If you deliberately run a reduced mode, no third parties until consent for instance, then say so alongside the number and compare like with like.
Bundles: Import Boundaries Rather Than Chunk Counts
A CMS catch-all route can statically reference every section component that might ever appear, and that’s how an application ends up shipping an editor nobody on this page is going to open. But the important correction comes first: splitting chunks does not make statically imported code lazy. Manual chunk configuration changes grouping and cache reuse. What decides whether code is needed during startup is the import graph.
Look at what went unused. Record a coverage profile over a representative journey rather than just the first screen, because a module that goes unused at first paint may well be needed by the first interaction, and deferring that one makes the page worse.
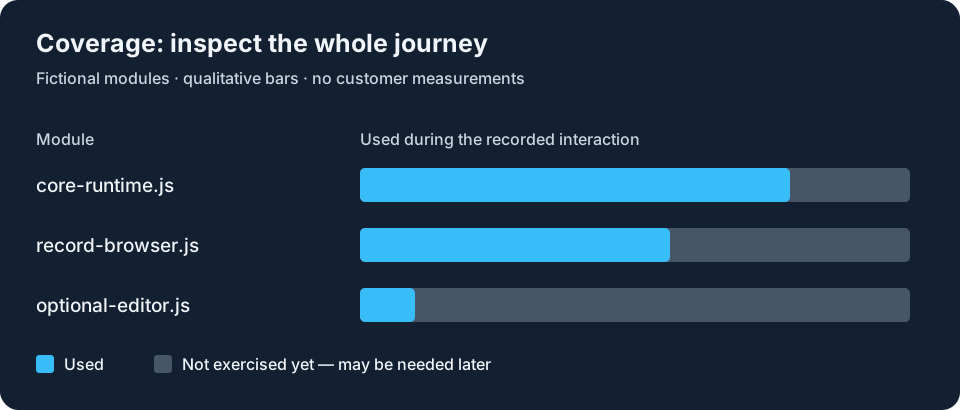
Illustration, not a captured measurement. Bar lengths are qualitative.
Then look at why it was included. The build analyzer shows you which import dragged a large dependency into the initial bundle, and that’s usually rather more surprising than the size itself.
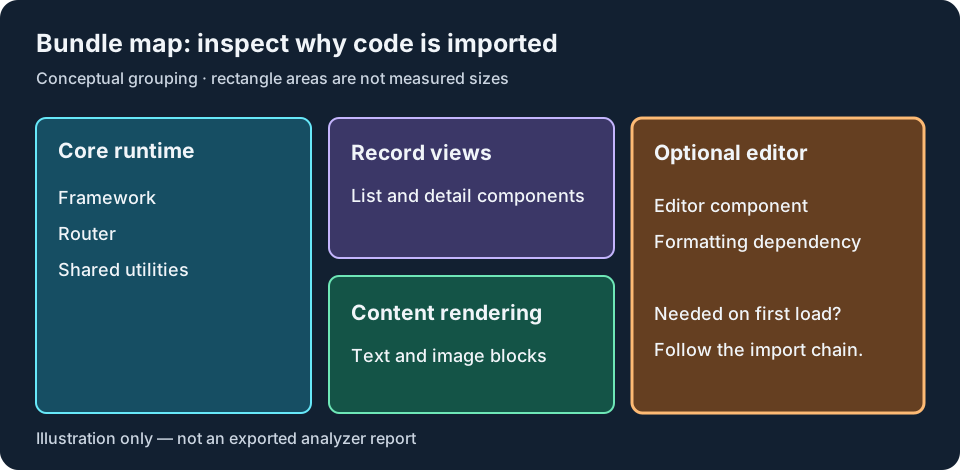
Illustration, not a production bundle report. Areas are not measured sizes.
Then move the boundary. A dependency needed only by an optional editor belongs behind a dynamic import:
const LazyEditor = defineAsyncComponent(() => import('@/components/ExampleEditor.vue'))
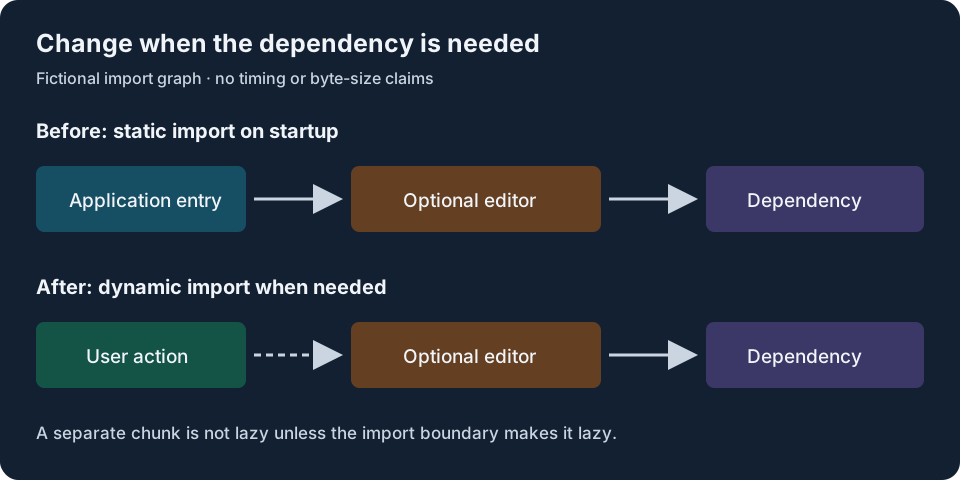
Illustration of an import boundary, not a measured byte reduction.
There are four checks worth making routinely.
Use type-only imports (import type { … }) wherever you need a type rather than a value, so the bundler removes the statement altogether instead of keeping a whole module in the graph for the sake of one type annotation.
Verify what your barrel files contribute to the output. A barrel is an index.ts that re-exports a folder’s contents so consumers can write a single import. The cost is that importing one symbol from it references the whole module, and the bundler can only drop the rest if tree-shaking, the elimination of exports nothing reaches, can prove that dropping them changes nothing.
That proof is a lot easier to defeat than it looks, and the thing that defeats it is a side effect at import time: work a module performs merely by being evaluated, rather than when something calls into it. A module whose body only declares functions, classes and constants has none. A module that registers a global listener, patches a prototype, writes to window, installs a polyfill, reads configuration at load, or imports a stylesheet does have one, because evaluating it changes something outside itself.
// analytics.ts
window.addEventListener('error', reportError)   // side effect: runs on import

export function trackRevisionSwitch() { /* ... */ }
If nothing in the application ever calls trackRevisionSwitch, then that function is unreachable and could be removed. The listener registration can’t be, though, because dropping the module would change how the page behaves. And a bundler has no way of telling those two cases apart from the outside, so its safe default is to keep the module and evaluate it.
Declaring a package side-effect-free is how its author waives that caution. The sideEffects field in package.json states that evaluating the package’s modules does nothing observable, so a bundler is free to discard the unused ones outright rather than merely stripping their unused exports:
{ "name": "example-ui", "sideEffects": false }
It can also name the files that do have effects, and "sideEffects": ["**/*.css"] is the usual case there, since a stylesheet import exists precisely for its effect. A package that omits the field says nothing at all, and a bundler reads that silence as “assume every module might matter”, so each one reachable through the barrel gets kept and evaluated however little of it you actually use. One such dependency sitting behind one re-export is enough to drag the whole folder it lives in into your bundle. So read the build output rather than assuming.
Keep server-only modules out of browser import paths, and avoid one oversized vendor chunk that makes completely unrelated features load together.
And after you introduce any lazy boundary, go and exercise the route transitions and the first interaction, because a bundle report can’t tell you what that boundary cost. A report describes the build output: which modules ended up in which chunk, and how large each chunk is. Moving the editor behind a dynamic import improves that picture by construction, since its code is no longer in the initial bundle, so the initial bundle is smaller and the number is perfectly correct. What a report has no way of expressing is when the chunk arrives relative to when somebody needs it. The code didn’t stop existing. A request, a download, a parse and an evaluation got moved to the moment the button is pressed, and on a constrained connection that sequence is long enough to notice.
So the regression looks like this. A visitor presses Edit, nothing visible happens, and they press it again. Nothing was broken and no click got swallowed by a bug. The component that would have handled it simply hadn’t loaded yet. The build output is right, the report is right, and the problem lives in the timing between the two. Only actually using the application surfaces it, which is why this check has to be a behavioural one: trigger each lazy boundary immediately after paint with network throttling on, and decide per component whether that wait is acceptable.
Rewriting the Rendered HTML
Nitro’s render:html hook can modify the final server output, which makes it a very tempting place to rewrite resource URLs or reorder scripts. It’s also a string-level dependency on framework output, which is rather less comfortable.
If you do use it, preserve script attributes, content-security-policy nonces and escaping, and remember that a replacement written for one attribute form is going to miss srcset, encoded URLs and anything generated later in the browser. Prefer structured hooks and URL helpers wherever they exist, and test against a production build, because the development server emits different assets and a passing dev test therefore proves rather less than it appears to.
Verifying the Combined Result
Optimizations interact with each other, and not always favourably. Deferring code improves a startup measurement and can push the cost straight into the first click. Aggressive caching improves the warm path and can leave the cold path worse off, because more work is now bundled into the one request that misses.
A small matrix is enough to catch most of that: cold and warm caches, an ordinary device profile and a lab profile, both consent states, the main routes, and the critical interactions on each of them. Server behaviour under concurrency is a completely different experiment with different tooling, and that’s Part 19.
The conclusion a matrix like that supports is specific and modest: these changes reduced this kind of work under these conditions. That’s a defensible claim, and it’s the only kind available to you here. There’s no guaranteed score, no universal latency saving, and no formula that combines several optimizations into a predicted total.
So here’s the diagnostic to carry out of this article. Before you change anything, write down which of the three kinds of waiting you’re fixing and the measurement that shows it. If you can’t, then your next change is a guess, and in performance work a guess is very easy to mistake for a success, because after almost any change at all some number looks better than it did before.
What’s Next
- Part 14: Deferred Hydration — Choosing what may wait, judged by first usable interaction rather than by a score.
- Part 15: Security in a Nuxt SSR App — The trust boundaries that survive moving code to the server.
Munir Husseini is a software architect specializing in full-stack TypeScript, .NET, and cloud-native architectures.
Category: Nuxt in Production